01
Navigate to any page with PDF documents
Visit an academic site, government portal, legal database, or any webpage that links to or embeds PDF files.
Instantly download research papers from academic sites, even when download buttons are hidden.
Academic databases and university repositories often display papers in embedded viewers that lack a direct download option. PDF Downloader scans these pages and detects PDFs hidden behind JavaScript-based readers, letting you save them in one click. You can batch download multiple papers from a single resource page, streamlining your literature review.
When available, the extension shows file size and page count before downloading, so you can prioritize what to save. This is especially handy when working with large collections of articles, theses, or conference proceedings. You avoid the frustration of opening each document just to find out it's not what you need.
Your downloaded PDFs retain all original formatting, images, fonts, and vector graphics. Build a reliable offline reference library for your research, accessible anytime without an internet connection.
Trusted by 40k+ SERP Apps users.
Private downloads. No ads or tracking.
Part of the SERP Apps Extensions Library.
Open the page, let the extension detect what is available, and save the file to your computer.
Visit an academic site, government portal, legal database, or any webpage that links to or embeds PDF files.
The extension detects PDF files linked directly, embedded in document viewers, or loaded through JavaScript-based readers on the page.
Review the list of detected PDFs with file size and page count information. Choose individual files or select all for batch download.
Short, practical feedback from people using PDF Downloader in real workflows.
I work in legal research and many court filing sites only show PDFs in a viewer without a download option. This extension finds the file URL and downloads the actual PDF. It has become essential to my workflow.
Wendy Garrison
2025-02-12
Academic papers embedded in viewer-only interfaces are frustrating. This tool grabs the underlying PDF so I get the full document with all formatting intact for my reference library.
Rajan Mehta
2025-03-03
Government sites are notorious for terrible PDF download experiences. This extension detects every document on the page and lets me batch download entire policy libraries.
Diane Calloway
2025-01-28
These comments and ratings were collected during our July 2026 customer survey and reviewed against support records before publication.
Core capabilities included in PDF Downloader.
Identifies PDFs on webpages whether they are linked directly, embedded in the page, or loaded via scripts.
Captures PDFs from interfaces that present documents without offering a visible download option.
Retains the original layout, pictures, typefaces, and scalable vector artwork in every file.
Fetch several PDFs found on one page at the same time.
Performs reliably on scholarly repositories, official government sites, legal research platforms, and internal corporate networks.
Displays the document size and number of pages before you decide to start the download when that data exists.
Built for Chrome, Firefox, Edge, and Opera across Windows, macOS, and Linux desktops.
Go to any location that hosts PDF content, like a university library portal or a municipal records archive.
Open the extension and let it scan the page for PDFs delivered as links, embedded objects, or script-driven readers.
Review the surfaced files along with size and page details, then pick which to save.
Each PDF is saved straight from its origin server, protecting every formatting detail, image, font, and vector element.
Collect academic articles, court submissions, and agency documents without relying on manual copy-and-paste steps.
Save PDFs directly in your browser instead of copying links to another website.
PDF Downloader Extension
Files save straight from the origin server
Using a Separate PDF Website
You submit the page address to another service
PDF Downloader Extension
Built-in progress bar for every download
Using a Separate PDF Website
Progress depends on the external site's interface
PDF Downloader Extension
Works without leaving the current page
Using a Separate PDF Website
You must visit a separate downloader website
PDF Downloader Extension
Batch-save all detected PDFs at once
Using a Separate PDF Website
Batch handling may be limited or absent
PDF Downloader Extension
Shows file size and page count before saving
Using a Separate PDF Website
Pre-download details often unavailable
PDF Downloader Extension
Operates in Chrome, Firefox, Edge, and Opera
Using a Separate PDF Website
Access limited to browser-based web tools
Available on major desktop browsers and operating systems used in day-to-day workflows.
Pick the browser build you need. When a direct GitHub release is available, you can grab the ZIP there.
Chrome support is in progress and will be enabled soon.
Firefox support is in progress and will be enabled soon.
Edge support is in progress and will be enabled soon.
Opera support is in progress and will be enabled soon.
Brave support is in progress and will be enabled soon.
Whale support is in progress and will be enabled soon.
Yandex support is in progress and will be enabled soon.
Install from GitHub releases or your user dashboard. ZIP builds include the full desktop extension.
Every requested permission and the job it performs inside the extension.
Scans the current page for PDF files embedded in viewers, linked in the DOM, or loaded via JavaScript.
Saves detected PDF documents to your local downloads folder with original filenames.
Stores user preferences for download location and batch queue state between sessions.
Inspects page content and JavaScript-loaded document viewers to detect PDF file URLs that are not visible in the static HTML.
Better to know the boundaries up front than find out after checkout.
Password-protected PDFs still require the password to open after downloading
The extension does not remove or bypass PDF security restrictions
Detection depends on how the website embeds or links its PDF files
Some viewer-only interfaces may use image-based rendering instead of actual PDFs
Safari and mobile browsers are not supported
Files behind authenticated paywalls require a valid login session
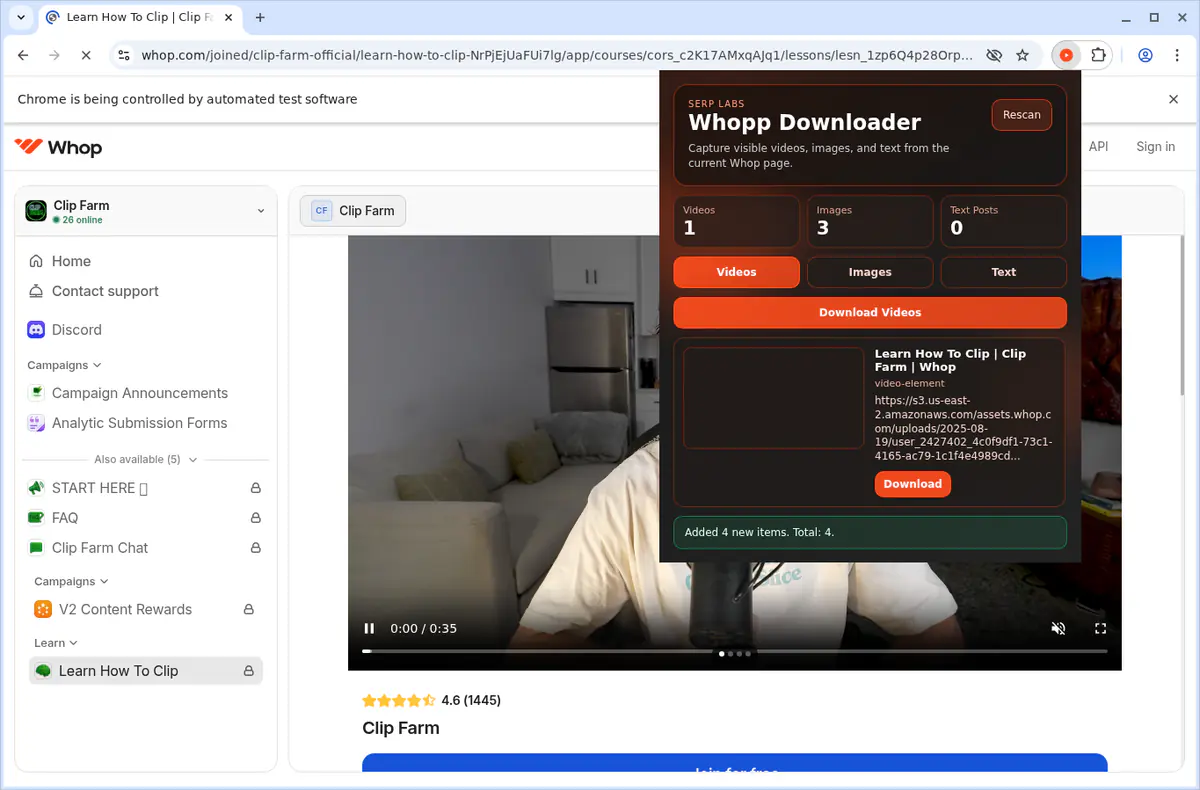
Download Whop videos from the lesson or post open in your browser. Find the video, scan the page, save the MP4, and check the result.

Learn when yt-dlp works with a Skool video provider URL, why lesson links often fail, and which workflow fits each player.

Download YouTube videos from the watch page, choose an available quality, and save the completed file to your computer.
Keep exploring
Browse every category we support and jump directly into the tools that match your workflow.
23 categories are currently available.
Immediate Access
Product access begins after a successful checkout
Setup Guidance
Installation steps are provided for the supported package
Billing Shown Upfront
Review the selected billing interval before checkout
Save research papers, legal filings, and government documents without copy-paste workarounds
Download PDFs from sites that only show a viewer without a download button
Batch grab multiple PDFs from resource pages or document libraries
Keep an offline reference library of technical manuals, whitepapers, and reports